KnowledgeForge – GraphRAG PDF Chat
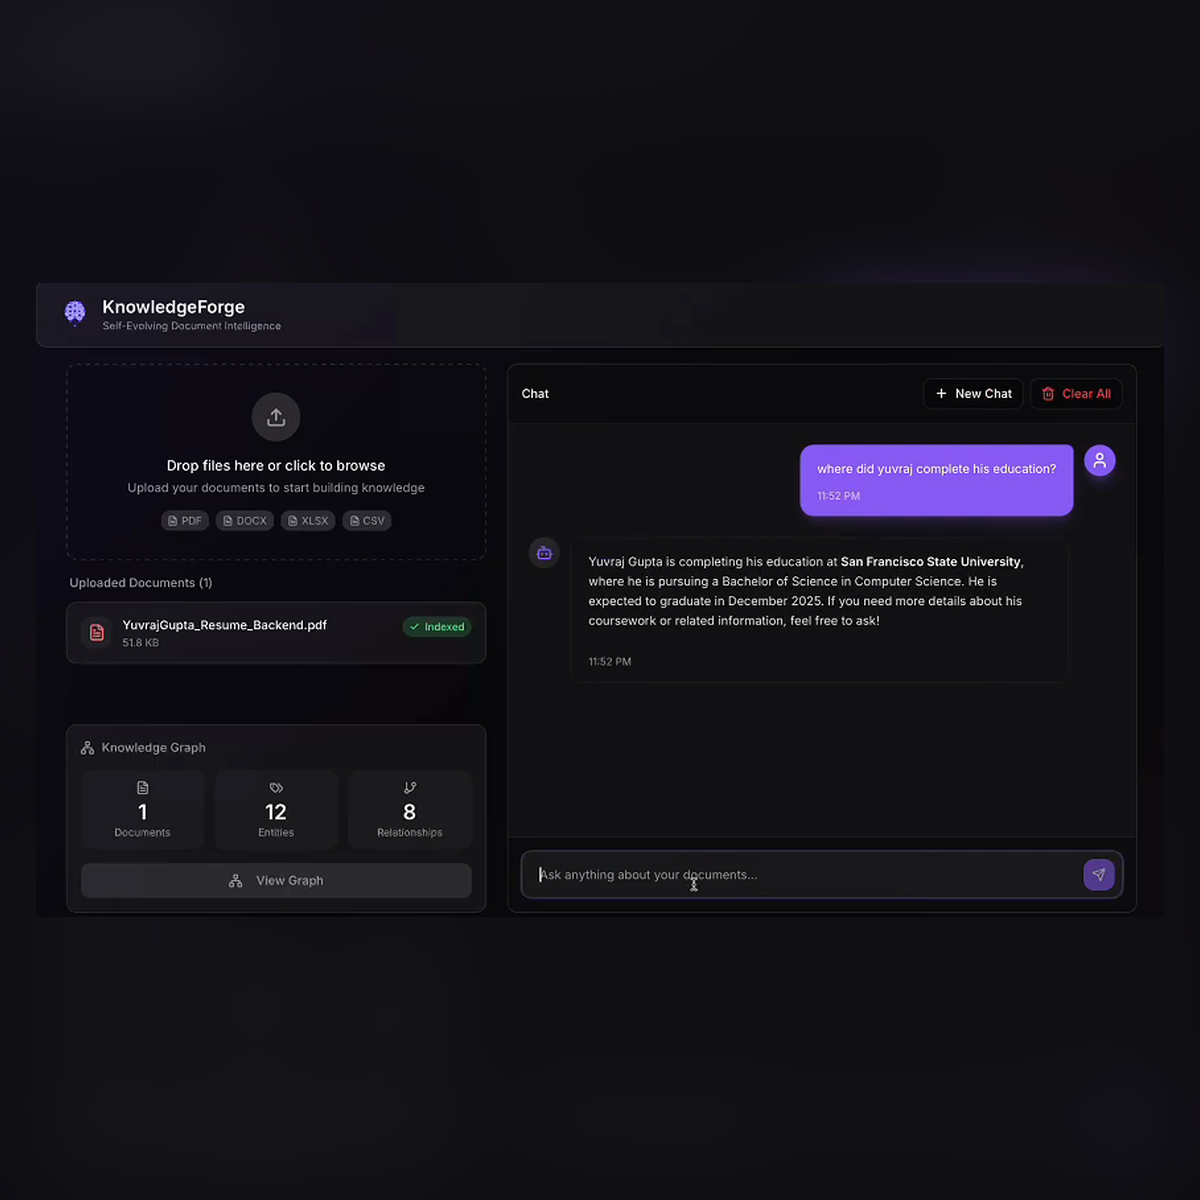
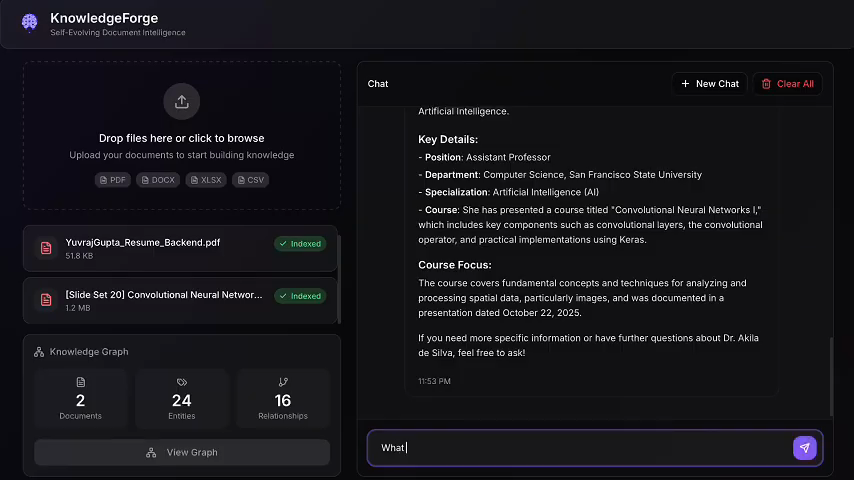
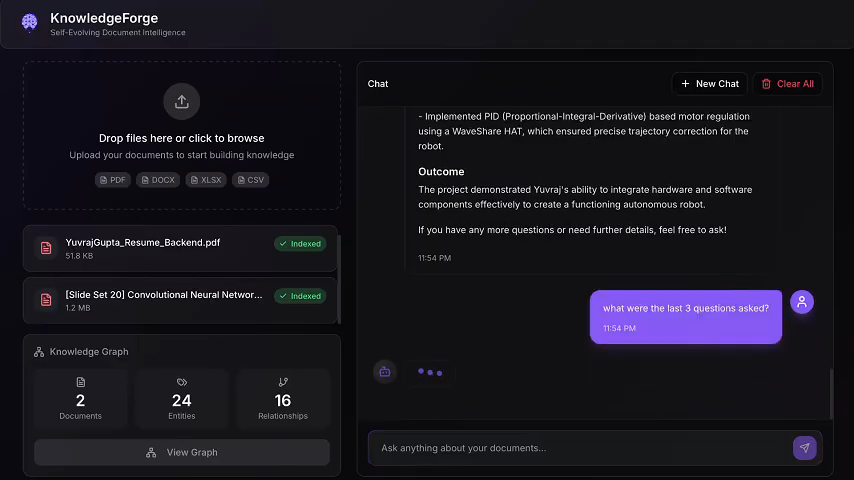
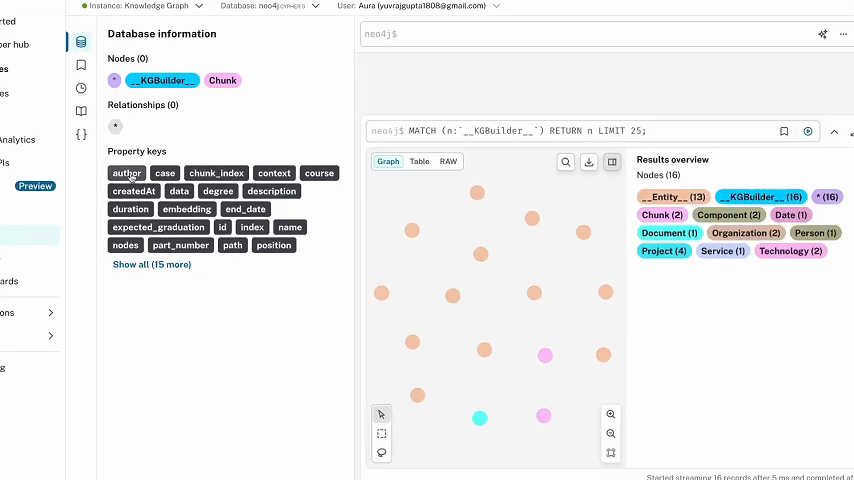
Built with Pramod Thebe and Ryuto Kawabata. A PDF chat system that gets smarter as you upload more documents. Instead of retrieving the top-K similar chunks, it extracts people, organizations, locations, dates, and concepts, links them in a Neo4j knowledge graph, and answers questions by traversing that graph across multiple hops, which is what you need when the answer spans several PDFs or depends on how things relate. A MemMachine-style memory layer decides what stays short-term and what is promoted to episodic memory so the conversation stays coherent across sessions.
Project Features
Entity and Relationship Extraction
Every uploaded PDF is mined for entities and the relationships between them, then merged into a graph that grows with the library.
Multi-Hop Retrieval
Questions like who or what is related to X across these documents are answered by walking edges, not by hoping the right chunk ranks first.
Layered Memory
Short-term, episodic, and semantic memory are kept apart. The agent can explain an answer by pointing at the memory path it used.
Reproducible Deployment
Neo4j, the ingestion service, and the chat API come up together in Docker, so the demo is the same on every laptop.
Project Info
12/2025
Graph Retrieval & Memory Layer
Team of 3
Completed
Technologies Used
- • Python
- • Neo4j
- • GraphRAG subgraph retrieval
- • MemMachine memory layer
- • Strands Agents SDK, OpenAI API
- • Docker
Watch It Run
KnowledgeForge demo
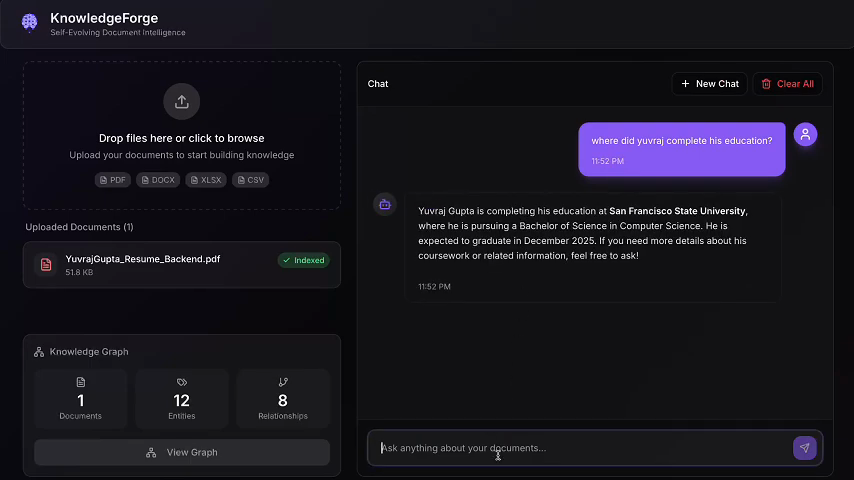
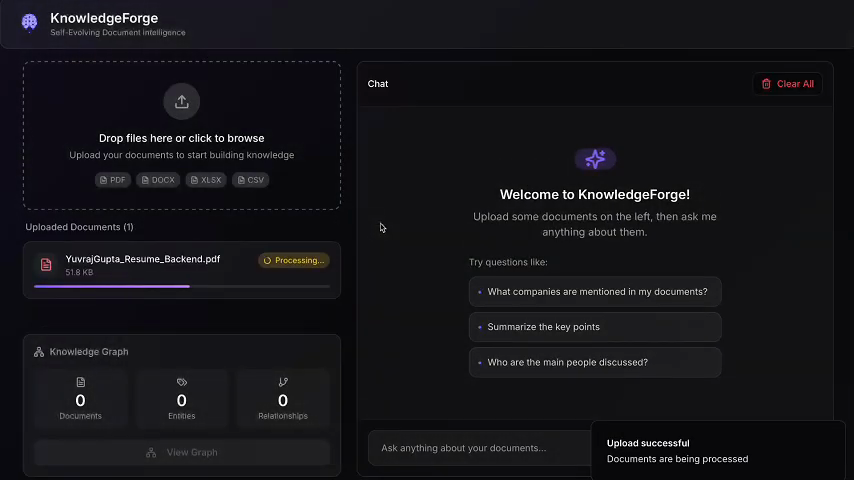
Uploading PDFs, watching the entity graph grow in Neo4j, and asking questions that span documents.
Project Gallery
Interested in This Project?
I'm always excited to discuss my projects and share insights about the development process. Feel free to reach out if you'd like to know more!